open source · spec-driven TDD · for Claude Code
The memory + seatbelt
for your AI coding agent.
Your agent writes the code. mokata makes it prove the code is right: no implementation until every acceptance criterion has a failing test, gates that block the agent's own edits, a review checked back against the spec — and a record of every decision. Nothing leaves your machine.
pip install mokata && mokata setup claude
› /mokata:brainstorm add retries to fetch()

✓ run registered      bound to this session · parallel-safe
✓ approach approved   by you · prior art checked
✓ spec emitted        4 acceptance criteria → 4 tests
✓ red                 4 failing — as they should

✗ BLOCKED [spec-scope] sed -i … src/billing.py
  outside what the spec authorised — amend it, or leave it

✓ green               31 passed · 0 skipped
✓ review              independent ✓ · checked against the spec
⏸ AWAITING APPROVAL   waiting on a human — not an error
// why mokata
Rules files are advice. Gates are code.
A prompt or a rules file asks the model to behave, and you find out in review whether it did. mokata moves the rules out of the prompt and into the path of the write: a hook that blocks it, an approval only a human can mint, a ledger that records it.
Write, Edit or the shell.
// how it works
One run, from the idea to the merge.
Each stage has a gate. A stage you skip is a write that gets blocked, not a step that gets forgotten.
- 01
Brainstorm
Socratic questions, prior art, a pre-mortem — then you approve one approach.
gate · approach approved - 02
Spec
Acceptance criteria, each mapped to a test, persisted. A deferred item can't be built later without an amendment.
gate · spec + completeness - 03
Red
The tests fail first — proof they can catch the bug before the fix exists.
gate · no code without a failing test - 04
Green
Implementation inside the spec's scope only. Native edits and shell writes meet the same gates.
gate · spec scope - 05
Review
Checked back against the spec — by a fresh subagent when one is observed, and said plainly when it wasn't.
gate · verdict on record - 06
Ship
Tests green, criteria met, review passed — then you choose how it lands. mokata never merges for you.
gate · you decide
// what you get
Four jobs, one governed engine.
The agent can't skip the process
- Gates on native edits. Enforced by a hook on the agent's own
Write,Editand shell commands — not only on mokata's tools. A shell write meets the same verdict as aWrite; a command mokata can't read is refused while a run is in progress. - Parallel runs, kept apart. Each Claude session is bound to its own run, so two windows working on two features never police each other.
- Subagents under contract. A read-only explorer stays read-only, nesting is capped, and every subagent hands back a structured report.
- Survives compaction. After
/compactthe gate state is re-stated from the record, so a long session can't forget it.
Know what the change touches
- A mandatory codebase graph. Blast radius answered structurally, not by grep. An embedded AST floor ships in the box; a stale graph rebuilds before it answers; a degraded answer is refused as decision input.
- The review window.
mokata ideshows what each session wrote, the diff at any point in time, branch-to-branch and PR comparisons — read-only, localhost, paired. - Live context. The briefing carries the repo's current state and the run's working set, inside one context budget you control.
Memory you can trust
- Can't be poisoned. Typed memory — rules, guardrails, decisions — and no code path that writes it without a human-minted approval.
- Session notes you approve. At the end of a session mokata drafts a note from the record; it's kept only if you accept it.
- Ages without losing anything. Bi-temporal validity: archiving closes a window instead of deleting a row.
- Retrieval that tells the truth. Ranked in the database (FTS5 / tsvector), semantic on consent, and
mokata doctorsays which engine is ranking.
Every decision on the record
- A typed event stream. Every gate verdict, approval and durable write — reconstruct any run: what changed, why, and who approved it.
- Review you can measure. How many problems were caught in the loop and how many only at review, per run.
- Waiting is legible. Every call is bounded; a gated write says AWAITING APPROVAL instead of going silent.
- Token governance. One context budget, JIT retrieval, handback caps, output density on by default.
// new · mokata ide
A window onto everything your agent wrote.
Agents write faster than anyone can read a terminal. mokata ide is where you check their work: what each session changed, when, and how it compares — on your machine, read-only, opened from inside the session with /mokata:review-window.
mokata ide --demo
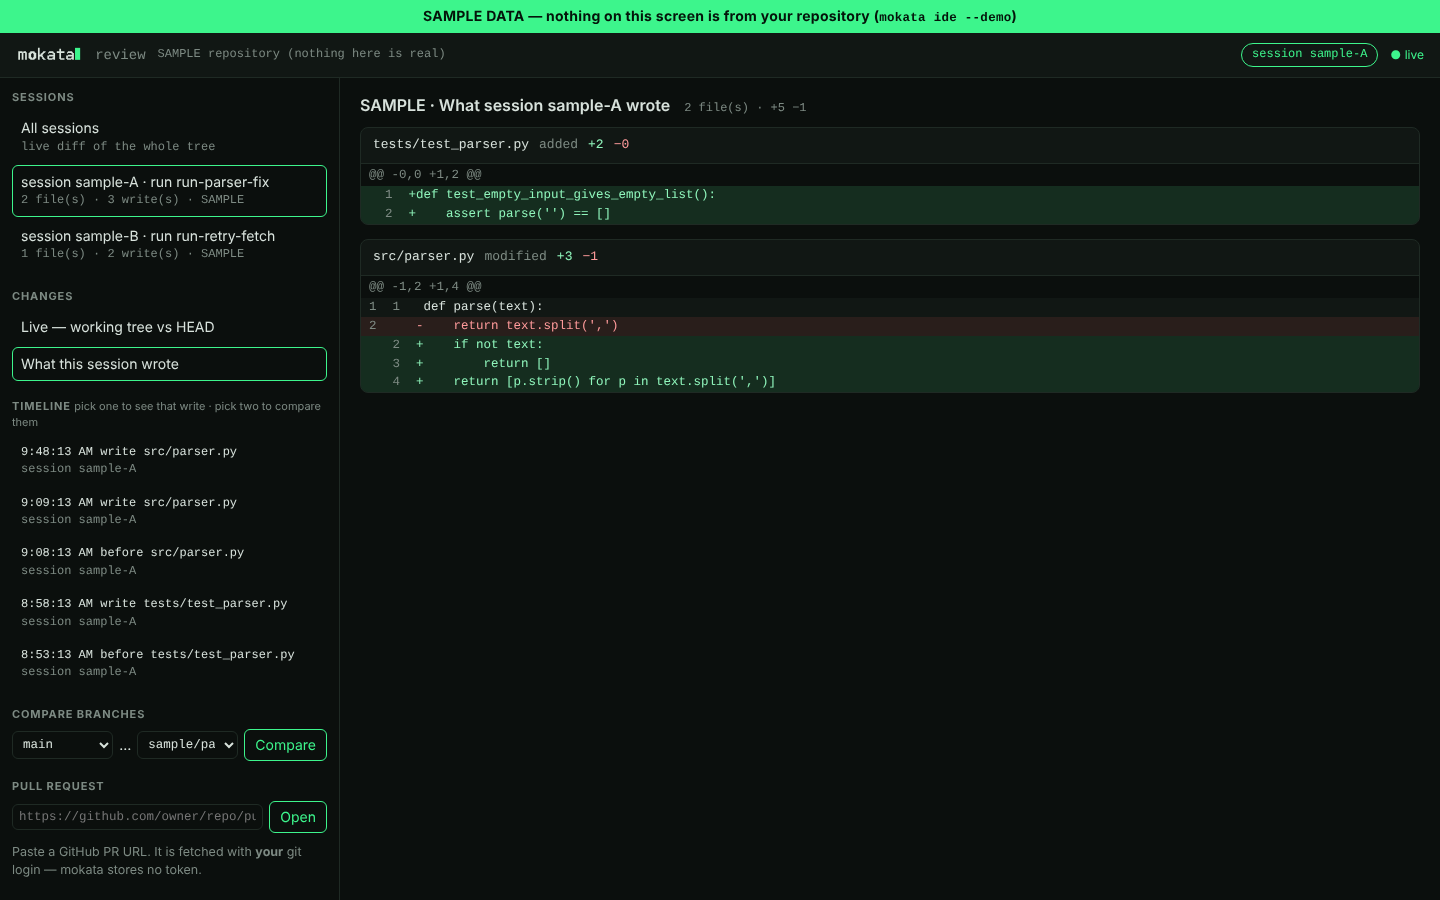
--demo).Per session
What each Claude session wrote, file by file — the content before its first write against its latest. Parallel sessions stay separate.
Any point in time
mokata snapshots every write. Pick one to see it, or pick two and diff any two moments of the session.
Live, branches and PRs
The working tree against HEAD as it changes, two branches, or a GitHub PR by URL — fetched with your own git login.
Private by construction
Loopback only, a one-time pairing link, Host and Origin checks, and nothing read outside the repository. It never writes your code.
// see it in action
Skills, explained in one video
// running in a minute
Install, wire, run
pip install mokatamokata setup claude— wires the hooks, commands and MCP server/mokata:brainstorm <what you want>— in Claude Code
Adopt it gradually: mokata init --mode seatbelt gives you the gates and the graph, --mode memory adds typed memory, --mode full turns everything on. mokata never calls a model itself — the brain always comes from your harness.
// what ships in the box
At a glance
16 curated · 14 domain
wired into Claude Code
harness-independent
46 read · 23 write · 1 approve
5 enforced on native writes
the MCP SDK
// what's coming
Where mokata is going.
The review window grows into the place you supervise agent work — see it, check it, steer it, approve it — while the engine keeps tightening. Direction, not dates: a feature ships when its gate is green, and the changelog is the record.
mokata ide
- shippedThe review window
Per session, any point in time, live, branches and PRs.
- nextNavigate and search the code
Definitions, references, callers and callees; word and semantic code search — local, no API key, and an honest note when the semantic model isn't installed.
- in designBlast-radius map
The changed symbol at the centre, rings by hop, covering tests on the outside — untested paths flagged before you approve.
- in designCriterion → test → code, drawn
Every acceptance criterion traced to its tests and the code they cover. A criterion with no test, or code with no criterion, shows in red.
- in designReview and approve in the window
Findings per hunk, tied to the criterion they serve, and human-minted approvals without going back to the terminal.
- in designSession browser and replay
Every agent session — what it read and wrote, which gates fired, what it cost — replayable, with a marker on any session that is waiting for you.
- exploringQuick edits, still gated
Small human fixes on agent output, written through the same human-write channel: secret scan, conflict check, ledger entry.
the engine
- nextCheaper long sessions
A context prefix that stays byte-stable across turns, so the harness's prompt cache keeps paying off.
- in designWorktree and session management
Tools to list, switch and clean up the worktrees and sessions that parallel runs leave behind.
- in designClearer output, never stuck
Every command answers with what happened and what to do next, and nothing waits without saying why.
- pendingOne-click plugin install
mokata in the Claude Code plugin directory, once approved. The pip-first path works today.
Does mokata call a model or need an API key?
No. mokata never calls a model — the brain is always the agent you already run. There is no model and no API key inside mokata.
Does my code leave my machine?
No, unless you wire something that sends it. State lives under .mokata/ in your repository; team mode and sharing are opt-in, and they pass the same secret scan as every write.
What happens when a gate blocks something I want?
The block says why and what to do: approve an approach, amend the spec, add the failing test. A run-state gate can be overridden with a reason, and the override is recorded. Security blocks — a secret in the content, a write outside your workspace — cannot be overridden.
Do I have to adopt the whole pipeline?
No. mokata init --mode seatbelt gives you the gates and the graph; add memory later, or turn everything on with --mode full.
Which agents does it work with?
The full set — gates on native edits, subagent contracts, the review window per session — is Claude Code. Codex, Cursor, Copilot, Windsurf and Gemini CLI get mokata's commands, context and MCP server, and mokata says plainly what degrades.
Put the seatbelt on.
pip install mokata && mokata setup claude
About mokata
mokata is an open-source framework for Claude Code that brings the strongest ideas in
AI-assisted coding into one governed engine. It brainstorms the problem with you, drafts a
spec, refuses to write code until every acceptance criterion maps to a test (RED before
GREEN), and reviews the result back against the spec. Around that engine sit a codebase
graph that is mandatory by default (an embedded stdlib-AST floor ships in the box, so
blast radius is answered structurally rather than by grep), typed persistent memory with
in-database lexical recall and an optional consented semantic tier, active token governance,
and a full audit trail — with every durable write human-gated (the model proposes; you
mint the approval in your own terminal with mokata approve <id> — a model can never approve
its own write) and nothing leaving your machine unless you wire it.
Five of those gates are enforced by a hook rather than by mokata's own tools, so they hold for
your agent's native edits too: no approved approach, no persisted spec, no failing test, or a
write outside the scope the spec authorized, and the write is blocked outright — and ahead of all
four, self-protect refuses any write to an installed package tree or outside your workspace at
all. And because no code path writes memory without a human-minted approval, mokata's memory
cannot be poisoned by content you never approved.
It keeps working when the session gets long or busy. Each Claude session is bound to its own
run, so parallel sessions never police each other; after /compact the gate state is re-stated
from the record; a shell command meets the same gates as a native edit; and a subagent works under
a contract — read-only stays read-only, and it hands back a structured report. To see what any
session actually wrote, /mokata:review-window opens the review window — a read-only page on
your machine with the diff of each session, any point in time, branches and PRs
(Review what your agent wrote).
You don't have to adopt all of it at once — mokata init --mode seatbelt wires just the gates
and the graph, --mode memory adds persistent memory, --mode full turns on everything.
mokata is pure Python (≥ 3.10) — the engine is stdlib-only, and the MCP SDK is its single runtime dependency, so the MCP server works out of the box. It is Apache-2.0 under MoStack, and is built clean-room (no dependency on any other framework).
Start here → Getting started. One instruction sets mokata up and
updates it — in your repo run uv tool install --upgrade mokata (or pipx install --force mokata),
then mokata setup claude → restart Claude Code → mokata doctor. setup claude runs
mokata init for you on a new repo and only refreshes the wiring on an existing one. The
alternative is the Claude Code plugin — inside Claude Code run
/plugin marketplace add JasGujral/mokata-oss, then /plugin install mokata@mostack (its MCP
server starts through uvx, so uv must be on PATH). Plain pip install mokata works too, last:
inside a project venv this mixes mokata's deps into yours — prefer the above.
mokata never calls a model itself — the brain always comes from the harness. For why there are two ways to run it (and which fits your goal), see How mokata uses an LLM: harness vs CLI.
What's here
This site follows the Diátaxis model:
- Getting started — install and run your first pipeline in minutes.
- Tutorials — mokata catches a bad change: a 60-second copy-paste walkthrough — run it in your own terminal and watch the seatbelt catch a bad change; differentiators in action: a runnable demo of every differentiator (graph, memory, governance — see them work); run a story end-to-end: a guided, learn-by-doing walkthrough; and the Complete Guide: every command, gate, and layer (with a downloadable PDF).
- How-to guides — task recipes: configure a profile, set the execution mode, use & heal memory, write a skill, review what your agent wrote, integrate other tools, share a stack, run mokata as a team (setup & operations), install the Claude plugin, use mokata without the plugin.
- Concepts — how each layer works: the pipeline & gates, knowledge layer, memory, token governance, execution modes, governance & audit.
- Reference — complete specs: CLI, manifest & configuration, skills catalog.
- Developer guide — architecture, dev setup, testing, contributing.
The feature set at a glance
| Part | Area | Highlights |
|---|---|---|
| A | Spine | manifest, capability router, detection + graceful degradation, bootstrap, init (incl. the --mode seatbelt\|memory\|full on-ramp); upgrade refreshes the harness wiring through setup's own preview-diff gate, and stale wiring is visible on three channels (doctor --wiring exits non-zero, and works before init) |
| B | Knowledge | codebase graph mandatory by default — embedded stdlib-AST floor in the box, adopted graphs layered on top, grep beneath; a degraded blast radius is refused as decision input unless a ledgered escape is accepted; typed queries, incremental index + staleness, drift anchors |
| C | Memory | typed persistent / decision / episodic memory, self-healing (surfacing), no auto-writes — the poisoning defense; in-database lexical recall (SQLite FTS5 + bm25, Postgres tsvector + ts_rank) with an optional consented semantic tier, doctor reporting which is live; it ages — usage signals + bi-temporal validity windows, and an over-budget scope gets a proposed archival sweep that closes a window rather than deleting a row; it stays fast as it grows — each tier nominates its shortlist in the database; two people writing the same fact produce a proposal, not a lost fact; summaries are drafted by the agent you are already talking to (no model embedded, no API key) and still gated; memory export/import backs it up to .mokata/backups/ |
| D | Engine | brainstorm → spec → test → develop → review → ship, each gated (brainstorm alone runs 7 gated phases); provable completeness gate, AC-mapper, pre-mortem, prior-art step, spec-compliance, dry-run; a deferred item needs a re-gated spec amend before it can be built |
| E | TDD & execution | RED-before-GREEN, model routing, bug/debug/optimize engines, execution-mode selector; a run can take its own worktree and branch — always offered, never automatic — and worktree list joins your worktrees against their sessions with a staleness verdict per row; worktree clean and worktree remove tidy them — previewed, human-gated, and never touching a live session |
| F | Token governance | tracker, JIT retrieval, handback caps, output density, budget, cache-stable prefixes |
| G | Rules & governance | 4-tier rules, taxonomy, sync/async hooks, Karpathy gates, rule-learning, skill authoring |
| I | Safety & audit | secret protection, human-minted single-use approvals, 15 backed gates (six of them frontend/backend domain gates run by mokata gate check) — and the hook stops 5 things on your agent's native writes (self-protect plus the four run-state gates), audit ledger, lethal-trifecta gate, revert, resume |
| J | Distribution | cross-harness boundary, shareable stack manifests, portable sessions (transport derived from the repo's mode); release-notes-check refuses the cut when the notes announce a different version than the tag, or quietly drop a fact the changelog declared as a known limitation |
| K | Config | per-layer/tool toggles, profiles, local-first, committed config, trust dial, doctor (incl. the DSN deep-check and retrieval-stack line), reset |
| L | Composability | standalone commands, mid-pipeline entry, direct skills, catalog, chaining, suggestions |
| M | MCP surface | 70 tools (46 read · 23 write · 1 opt-in approve), every call bounded with a timed_out status that names the operation, typed annotations, structured response_format, cursor pagination, and a loud AWAITING APPROVAL head so waiting-on-a-human never reads as a hang |
| + | Sessions & subagents | each Claude session bound to its own run (parallel-safe); the gate state re-anchored after compaction; one context budget; subagent contracts (read-only, depth, a structured hand-back); shell writes meet the same gates as native edits; session notes drafted from the record and kept only on approval |
| + | Review window | mokata ide + /mokata:review-window — a read-only, localhost-only page: what each session wrote, the diff at any point in time from mokata's own write snapshots, the live tree, branch compare and GitHub PRs by URL; re-focuses on the asking session; --demo sample data (guide) |
Counts in the box today: 30 Agent Skills (16 curated + 14 domain) · 38 slash commands · 71 CLI subcommands · 70 MCP tools · 15 backed gates · 1 runtime dependency.
Published docs: https://mokata.ai/ · Source & issues: https://github.com/JasGujral/mokata-oss.